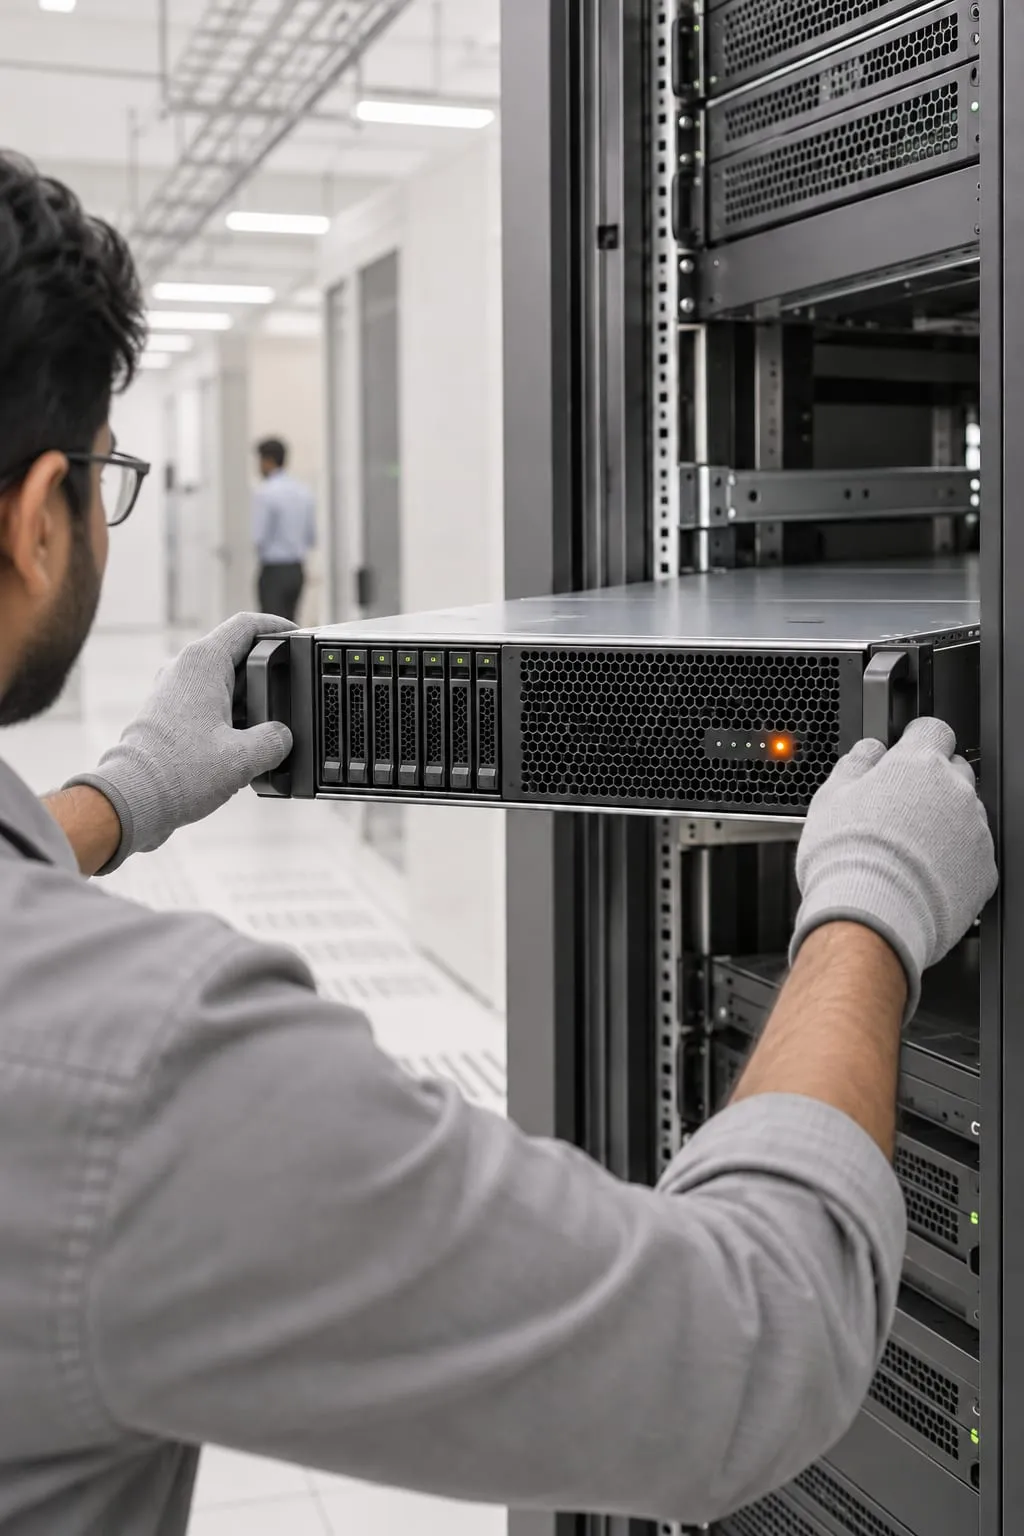
When does keeping servers on-site still make sense?
On-premise servers make sense when local performance, application requirements or control over physical infrastructure justify operating equipment yourself. Start with what must run locally and how you would recover it. Choose the vendor after that.
A factory application may need to continue working when its internet connection fails. A design office may move large files between workstations and shared storage throughout the day. An established business system may require a supported local database or hardware connection. These are concrete reasons to assess local compute, but none removes the need for maintenance and recovery planning.
Start with an application inventory. Record owners, supported operating systems, database dependencies and acceptable interruption. Measure busy periods as well as averages: a payroll run or reporting batch can expose a capacity limit that ordinary daytime use hides. Separate memory pressure from slow storage before choosing a larger processor.
DTech Global uses those findings to design the server setup and write the equipment specification. The result should explain which workloads share a host, which need isolation and which can move elsewhere. Keep a small deployment manageable. Extra infrastructure also brings extra administration, even when the equipment fits in one rack.
What drives the cost over three to five years?
The cost comparison must include facilities, software and ongoing operation across the same three-to-five-year period. Comparing a server purchase with only a cloud compute bill leaves out material obligations on both sides.
For on-premise infrastructure, include hardware, hypervisor and operating system licensing, backup capacity, electricity and cooling. Add warranty renewals, replacement components and the staff effort needed for patching and recovery tests. Existing rack space is useful, but an overloaded UPS or unsuitable room can turn apparent spare capacity into additional work.
For cloud services, assess workload hours, storage performance, backup retention, connectivity and data transfer. A workload that can shut down outside working hours behaves differently from a database that must run continuously. Write down the growth assumptions. Both options must account for the same future demand if the comparison is to mean anything.
Hybrid designs can place local workloads near users while keeping a separate recovery copy or selected services in the cloud. They also introduce identity, routing and recovery dependencies. Coordinate these decisions with AWS cloud services before buying local capacity that may duplicate another system.
Procurement should distinguish required capacity from optional expansion. Ask when memory slots, drive bays or network interfaces become limiting. Record warranty expiry and likely replacement timing alongside licensing renewal dates. A cheaper initial purchase can create an expensive migration if the platform cannot support the intended operating period.
What belongs on a server room readiness checklist?
A usable server room needs dependable power, controlled temperature and restricted access before equipment arrives. Rack dimensions alone do not establish that a room can support production systems.
During the site assessment, check the following and name someone to resolve each outstanding item:
- Confirm available electrical capacity and dedicated circuits with a qualified electrician.
- Check earthing and protective arrangements against applicable local requirements.
- Size the UPS around measured load, required runtime and shutdown behavior.
- Assess cooling for equipment heat output and operation outside office hours.
- Allow space for rack access, safe maintenance and future cable routes.
- Separate power and data pathways where the installation requires it.
- Restrict room access and record who can authorize entry.
- Assess water exposure, dust and appropriate fire protection with local specialists.
- Plan environmental alerts and identify who will respond to them.
- Verify delivery access, rack depth and the weight limits of the installation area.
A UPS provides a bridge through short interruptions or an orderly shutdown; it is not a substitute for a wider power continuity plan. Test what happens when its battery reaches the shutdown threshold. Cooling also needs attention during a power event because servers may remain running while room temperature rises.
For data center setup in Pakistan, site conditions and available facility support should shape the design. International projects need the same evidence from the local installation team. Photos help remote coordination, while electrical and environmental acceptance still require competent checks at the site.
Which virtualization platform fits the workload?
Choose virtualization around application support, licensing obligations and the people who will operate it. VMware vSphere, Microsoft Hyper-V and Proxmox VE can each suit a deployment, but their operating models and compatibility requirements differ.
| Platform | Reasons to evaluate it | Questions to resolve |
|---|---|---|
| VMware vSphere | Existing VMware operations and applications validated for that environment | Current commercial terms, hardware compatibility and required management features |
| Microsoft Hyper-V | Windows-focused operations and established Microsoft administration skills | Host and guest licensing, backup integration and clustering dependencies |
| Proxmox VE | KVM-based virtualization and a team comfortable with Linux administration | Application vendor support, support subscription needs and storage design |
Confirm current terms and supported combinations during procurement. A familiar platform can reduce migration effort, but familiarity should not hide unsupported hardware or a backup product that cannot restore the intended guests. Test application behavior on the selected target before scheduling the final move.
Decide on storage separately from the hypervisor. NAS provides file-based access, while a SAN presents block storage to connected hosts. Local storage may reduce shared infrastructure for a small installation, but it changes the recovery and failover design. Assess latency, usable capacity, controller resilience and network paths together.
For high availability, name the failures you expect the design to survive. Multiple hosts do not protect an application if they all depend on one unprotected storage system. Clustering may restart a virtual machine after a host failure, yet users can still experience an interruption. Decide which failures justify automatic recovery and which can use a documented manual procedure.
How should backups prove that recovery will work?
Backups should demonstrate that a usable application can be recovered within the business’s agreed priorities. A backup job can report success while leaving you unable to restore a working service. Test the recovered system with a user workflow.
The 3-2-1 rule is a starting point: keep three copies of data, across two media types, with one copy off-site. Define how that principle applies to the actual storage and backup products. Copies managed through the same compromised administrator account can remain exposed together even when they occupy different devices.
Set recovery point and recovery time objectives with application owners. The recovery point describes how much recent data the business could lose; recovery time describes how long restoration can take. These decisions influence backup frequency, replication and the amount of spare capacity required for recovery.
Test in an isolated environment where restored systems cannot accidentally send messages or overwrite production records. Validate database consistency, identity dependencies and access from a representative client. Record elapsed recovery time and any manual steps, including where the required credentials are held.
Replication and RAID serve useful purposes, but neither replaces an independent backup. Replication can carry unwanted changes to another system, while RAID primarily addresses certain drive failures. Recovery planning should also consider deleted files, damaged applications and lost administrative access. Protect the management paths through appropriate networking solutions and separately controlled backup access.
How long does it take?
A limited server replacement can take weeks once equipment and facilities are ready, while a room build or complex migration needs a longer staged schedule. Procurement, application testing and facility work often determine the completion date more than host installation.
Put the dependencies on the schedule before setting the cutover date. First confirm room readiness and equipment availability. Then allow for host configuration, storage checks, backup setup and a trial migration. Production cutover follows only after the application owner understands the test evidence and rollback options.
Data volume alone does not predict migration time. Transfer speed, small-file overhead, database consistency and permitted downtime all matter. A supported migration method may allow an initial copy while users remain active, followed by a shorter final synchronization. Other applications require a complete shutdown during the move.
DTech Global plans acceptance checks before production changes so everyone knows what completion means. For remote international work, local access windows and the availability of installation staff need explicit dates. Keep contingency time for failed components or application issues discovered during testing, and agree who can postpone cutover when a prerequisite remains unresolved.
How does DTech Global hand over an operable system?
DTech Global records the design decisions, makes changes in stages and runs agreed acceptance tests. Handover should give your team the access and operating instructions needed to manage the installed environment.
The record should include rack layouts, host inventories, storage mappings and network dependencies. Document firmware baselines, license ownership, warranty references and renewal responsibilities. Store passwords separately from general diagrams and transfer administrative access through an agreed secure method.
Write operating instructions for a normal morning and for a failed system. Explain how to identify a failed backup, shut systems down safely, replace a component through the supplier and restore a representative workload. Record exceptions with their business effect and an owner, rather than leaving unresolved assumptions inside installation notes.
Agree continuing support separately from project acceptance. Your staff may retain daily administration while managed IT services cover defined maintenance and troubleshooting tasks. Monitoring only helps when someone owns each alert and has authority to act. To review an existing room or plan a new build, contact DTech Global with your application inventory and current constraints.